Indie game storeFree gamesFun gamesHorror games
Game developmentAssetsComics
SalesBundles
Jobs
TagsGame Engines

You must be 18+ to view this content

Venus University may contain content you must be 18+ to view.

The creator of this page has specified that it contains mature themes and content. Please enter your birthdate to verify you are 18 or older:

or Return to itch.io

Venus University

A dating sim where you can say and do anything! Create characters and woo them while balancing university life. · By Venus Dev

v0.0.1 - Known Bugs, feedback, suggestions Locked

A topic by Venus Dev created 20 days ago Views: 1,181 Replies: 92
This topic was locked by Venus Dev 11 days ago
Viewing posts 1 to 20 of 26 · Next page · Last page
Developer (11 edits)

Hi VU students! Please use this thread to offer your feedback on the game:

  • What do you like? 
  • What's frustrating? 
  • Are there any features you want to see in the future?
  • Who's best girl?

I'd love to hear your thoughts! Venus University is currently in Early Access, so your feedback is invaluable to help me make a better game for everyone.

You can also include bug reports here or create a separate post on the main board for them, up to you. When reporting a bug, please include:

  • Where and when it happened
  • Screenshots if relevant
  • What provider/model you are using
  • Log file if you're comfortable sharing. You can grab a log file from the "Report a bug" button on the pause menu in-game or from Feedback on the Main Menu

Known Bugs:

  • You may get a SmartScreen warning about "unrecognized app" when downloading the game or opening it on Windows. Getting the game signed is way too expensive just to fix this, so you'll just have to trust that I haven't put a bitcoin miner in.
  • If you are getting "Connection to Gemini API lost" on free-tier Gemini keys, try downgrading the model to 3.5 or 3.6 in the settings.
  • If you are using local models and are failing to generate a course schedule, this is likely because your model is duplicating a course ID among the dozens of classes it's being asked to generate. I recommend using a frontier model to start your game instead, then switch back to your local backend (or use the Quickstart feature to skip class generation entirely)
  • Deepseek, Z.AI, and other APIs that don't support json_schema (expecting json_object instead) might not work with Venus University. If you want to use those models, I recommend accessing their models through OpenRouter instead.
Sara has light blonde hair in some pictures. I think that's a bug.

Developer

Hey Maboy, thanks for letting me know! I just patched this and it should be working in the new 0.03 version. If you're playing on desktop, you should be able to export your saves and import them into the new version.

Any plans for the next major update?

Developer

Most likely club activities, but the main goal right now is to fix bugs and hit 1.0. If you have anything you'd like to see, I'd be happy to hear suggestions

(+1)

Currently I'm making Characters so I can only give suggestions for that:

- More Options to make characters more unique with the ability to customize character personality deeper

- More control over NSFW scenes and maybe the ability to make your own with custom triggers

- Option for custom outfits

- More control for the image prompting for custom characters

Developer

Thanks! I'll keep these in mind for future updates. 

(+1)

Hallo! interesting game so far! quick question, will there be any possibility to allow local generated dialogues via koboldcpp?

Developer

Hi foxehtroppy! This is possible, but is a lower priority item for me. I spent a lot of time on koboldcpp with local models and don't think any would be smart/fast enough to handle the game's needs. Out of curiosity, what model would you be using with koboldcpp? And would you be willing to test the feature for me if I email you a build with it?

(3 edits) (+1)

Well the model I use is Cydonia-24B-v4.3-absolute-heresy.i1-Q4_K_M, is more in the NSFW side but so far it have been handling well enough and so far the bot doesn't go thirsty if I don't input any lewd stuff.

Speed wise: is more or less slow(1-3 words per second), sometimes go fast(maybe 4-6words per second) for some reason. but I dont mind the slowness.

Smartness wise it appears to handle decently when there are two or three characters (when using a CYOA char bot). I still need to check when using two bots in a group chat. Couple of times it got names the own model generated with the CYOA char bot.

And sure, though I suck in setting the min P and those type of parametes (I exported .json with those parameters already tweaked for Silly Tavern)


*But if it is a low priority it can wait :D

Developer

Cydonia-24B has been pretty good in my experience, though I did run into the same issue of it being a little slow, like you said. I will experiment with koboldcpp and add it in a future update if the quality is okay. Thanks!

hey if you need another tester for local Ilm, I got a 5060 to 16gb and so far I run 24 well in that area with fast speeds and even use an agent when I use marinara engine. I think the option of local would be awesome!

Developer

Hey ElPapaDon! I added local LLM support in v0.1.2. If you try it out, please let me know how it goes and what models work well

gotcha! ill give some feedback as i have today off so ill be touching upon this game alot xD

(1 edit)

What GPU are you using? I'm using the exact same model and quant, It's taking forever for me to load it up via llama.cpp on an RX 7900 XTX and I keep getting an error that it lost connection to the endpoint was lost mid-reply, is there something specific you did, what context size are you using?

(+1)

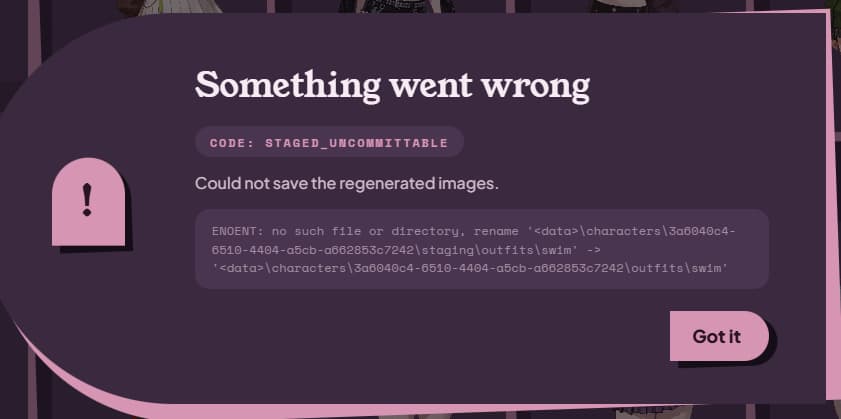
Hey! Just starting to try out the program, but during character generation, I get this popout:

At this point, only the default outfit was generated correctly. I don't think I've modified anything in the files/directories. Might upload a log file, when generation stops.

Developer (4 edits)

Hey Vdor01, thanks for reporting this! I ran into this myself during testing. I will look into this and fix it for the next minor update. I was able to work around this by restarting the game (your finished generations will stick around) and requeuing the outfit generation either from the Edit Character Modal or via "Generate missing content". If that still doesn't work, you might have to manually open the character's folder and create an outfits/swim folder. Please let me know if you still can't get it to work.

(+1)

Thanks, I solved it by moving the outfits folder out from staging. After that, it worked.

Developer

Great! Sorry about that, it's already been fixed for the next update

(+1)

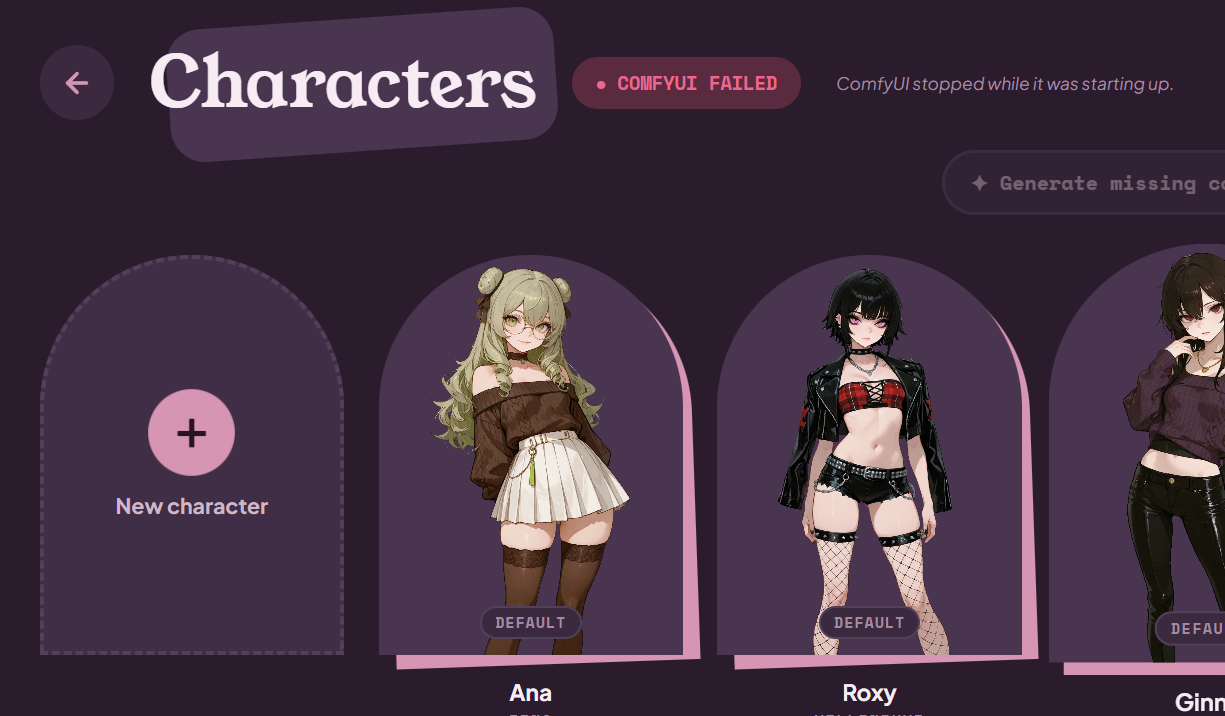
I downloaded the items at the first splash screen but now I just see this. I don't see an option to check my downloads.

Developer (1 edit)

Hey Bobgone! Can you provide the app.log file in your data folder (you can also download it by clicking Feedback on the main menu)? Or possibly copy over any ComfyUI related errors you see? It looks like ComfyUI installed properly but had an issue with starting up. This might happen if you don't have hardware that supports the ComfyUI installation we do, for example not having an NVIDIA GPU

Ah yeah I have an AMD GPU but I do have more than 8gb vram, will you be working on allowing an AMD version?

Below is the log from my last launch

2026-09-20 15:32:51.804 main     LOG   ==== Venus University 0.0.3 started ====
2026-09-20 15:32:52.808 main     LOG   [verify] starting setup verification
2026-09-20 15:32:52.808 main     LOG   [verify] checking ComfyUI portable runtime at <data>\services\comfyui
2026-09-20 15:32:52.808 main     LOG   [verify] checking 3 ComfyUI custom nodes
2026-09-20 15:32:52.808 main     LOG   [verify] checking model:upscaler at upscale_models/RealESRGAN_x4plus_anime_6B.pth
2026-09-20 15:32:52.808 main     LOG   [verify] checking model:handDetector at ultralytics/bbox/hand_yolov9c.pt
2026-09-20 15:32:52.809 main     LOG   [verify] checking model:faceSegDetector at ultralytics/segm/Anzhc%20Face%20seg%20640%20v2%20y8n.pt
2026-09-20 15:32:52.809 main     LOG   [verify] checking model:checkpoint at checkpoints/novaAnimeXL_ilV190.safetensors
2026-09-20 15:32:52.809 main     LOG   [verify] checking model:lora at loras/usnrStyle.safetensors
2026-09-20 15:32:52.809 main     LOG   [verify] checking model:controlnet at controlnet/illustriousOpenpose.safetensors
2026-09-20 15:32:52.809 main     LOG   [verify] comfyRuntime: missing (folder not found)
2026-09-20 15:32:52.809 main     LOG   [verify] node:impactPack (ComfyUI-Impact-Pack): missing
2026-09-20 15:32:52.809 main     LOG   [verify] node:impactSubpack (ComfyUI-Impact-Subpack): missing
2026-09-20 15:32:52.809 main     LOG   [verify] node:inspyrenetRembg (ComfyUI-Inspyrenet-Rembg): missing
2026-09-20 15:32:52.809 main     LOG   [verify] model:upscaler: missing
2026-09-20 15:32:52.810 main     LOG   [verify] model:handDetector: missing
2026-09-20 15:32:52.810 main     LOG   [verify] model:faceSegDetector: missing
2026-09-20 15:32:52.810 main     LOG   [verify] model:checkpoint: missing
2026-09-20 15:32:52.810 main     LOG   [verify] model:lora: missing
2026-09-20 15:32:52.810 main     LOG   [verify] model:controlnet: missing
2026-09-20 15:32:52.810 main     LOG   [verify] done — comfyReady=false (0/10 components ok)
2026-09-20 15:38:42.305 main     LOG   [verify] starting setup verification
2026-09-20 15:38:42.305 main     LOG   [verify] checking ComfyUI portable runtime at <data>\services\comfyui
2026-09-20 15:38:42.305 main     LOG   [verify] checking 3 ComfyUI custom nodes
2026-09-20 15:38:42.305 main     LOG   [verify] checking model:upscaler at upscale_models/RealESRGAN_x4plus_anime_6B.pth
2026-09-20 15:38:42.305 main     LOG   [verify] checking model:handDetector at ultralytics/bbox/hand_yolov9c.pt
2026-09-20 15:38:42.305 main     LOG   [verify] checking model:faceSegDetector at ultralytics/segm/Anzhc%20Face%20seg%20640%20v2%20y8n.pt
2026-09-20 15:38:42.305 main     LOG   [verify] checking model:checkpoint at checkpoints/novaAnimeXL_ilV190.safetensors
2026-09-20 15:38:42.305 main     LOG   [verify] checking model:lora at loras/usnrStyle.safetensors
2026-09-20 15:38:42.305 main     LOG   [verify] checking model:controlnet at controlnet/illustriousOpenpose.safetensors
2026-09-20 15:38:42.306 main     LOG   [verify] comfyRuntime: missing (folder not found)
2026-09-20 15:38:42.306 main     LOG   [verify] node:impactPack (ComfyUI-Impact-Pack): missing
2026-09-20 15:38:42.306 main     LOG   [verify] node:impactSubpack (ComfyUI-Impact-Subpack): missing
2026-09-20 15:38:42.306 main     LOG   [verify] node:inspyrenetRembg (ComfyUI-Inspyrenet-Rembg): missing
2026-09-20 15:38:42.306 main     LOG   [verify] model:upscaler: missing
2026-09-20 15:38:42.306 main     LOG   [verify] model:handDetector: missing
2026-09-20 15:38:42.306 main     LOG   [verify] model:faceSegDetector: missing
2026-09-20 15:38:42.306 main     LOG   [verify] model:checkpoint: missing
2026-09-20 15:38:42.306 main     LOG   [verify] model:lora: missing
2026-09-20 15:38:42.306 main     LOG   [verify] model:controlnet: missing
2026-09-20 15:38:42.306 main     LOG   [verify] done — comfyReady=false (0/10 components ok)
2026-09-20 15:51:59.183 main     LOG   [setup] skipping requirement not on the index: git+https://github.com/facebookresearch/sam2
2026-09-20 17:39:25.683 main     LOG   [verify] starting setup verification
2026-09-20 17:39:25.683 main     LOG   [verify] checking ComfyUI portable runtime at <data>\services\comfyui
2026-09-20 17:39:25.683 main     LOG   [verify] checking 3 ComfyUI custom nodes
2026-09-20 17:39:25.684 main     LOG   [verify] checking model:upscaler at upscale_models/RealESRGAN_x4plus_anime_6B.pth
2026-09-20 17:39:25.684 main     LOG   [verify] checking model:handDetector at ultralytics/bbox/hand_yolov9c.pt
2026-09-20 17:39:25.684 main     LOG   [verify] checking model:faceSegDetector at ultralytics/segm/Anzhc%20Face%20seg%20640%20v2%20y8n.pt
2026-09-20 17:39:25.684 main     LOG   [verify] checking model:checkpoint at checkpoints/novaAnimeXL_ilV190.safetensors
2026-09-20 17:39:25.684 main     LOG   [verify] checking model:lora at loras/usnrStyle.safetensors
2026-09-20 17:39:25.684 main     LOG   [verify] checking model:controlnet at controlnet/illustriousOpenpose.safetensors
2026-09-20 17:39:25.684 main     LOG   [verify] model:upscaler: ok
2026-09-20 17:39:25.684 main     LOG   [verify] model:handDetector: ok
2026-09-20 17:39:25.684 main     LOG   [verify] model:faceSegDetector: ok
2026-09-20 17:39:25.684 main     LOG   [verify] model:checkpoint: ok
2026-09-20 17:39:25.684 main     LOG   [verify] model:lora: ok
2026-09-20 17:39:25.684 main     LOG   [verify] model:controlnet: ok
2026-09-20 17:39:25.684 main     LOG   [verify] comfyRuntime: ok
2026-09-20 17:39:25.743 main     LOG   [verify] node dependencies: 6 names checked, none missing
2026-09-20 17:39:25.743 main     LOG   [verify] node:impactPack (ComfyUI-Impact-Pack): ok
2026-09-20 17:39:25.743 main     LOG   [verify] node:impactSubpack (ComfyUI-Impact-Subpack): ok
2026-09-20 17:39:25.743 main     LOG   [verify] node:inspyrenetRembg (ComfyUI-Inspyrenet-Rembg): ok
2026-09-20 17:39:25.743 main     LOG   [verify] done — comfyReady=true (10/10 components ok)
2026-09-20 17:39:28.782 main     ERROR [ipc] comfy:start failed: {
    code: 'COMFY_START_FAILED',
    message: 'ComfyUI stopped while it was starting up.',
    detail: '<data>\\services\\comfyui\\python_embeded\\python.exe exited with code 3221225477.\n' +
      "(4178 chars total) …_mxfp8', 'quantize_nvfp4', 'quantize_per_tensor_fp8', 'quantize_svdquant_w4a4', 'quantize_w4a8_int8_weight', 'rms_adaln', 'rms_rope', 'rms_rope1', 'rms_rope1_', 'rms_rope_', 'rms_rope_split_half', 'rms_rope_split_half1', 'rms_rope_split_half1_', 'rms_rope_split_half_', 'rotate_int8_convrot_weight', 'scaled_mm_mxfp8', 'scaled_mm_nvfp4', 'scaled_mm_svdquant_w4a4', 'stochastic_rounding_fp8', 'w4a8_int8_linear']}\r\n" +
      '\x1B[32m[INFO]\x1B[0m Checkpoint files will always be loaded safely.\r\n' +
      'Windows fatal exception: access violation\n' +
      '\n' +
      'Stack (most recent call first):\n' +
      '  File "<data>\\services\\comfyui\\python_embeded\\Lib\\site-packages\\torch\\cuda\\__init__.py", line 529 in _lazy_init\n' +
      '  File "<data>\\services\\comfyui\\python_embeded\\Lib\\site-packages\\torch\\cuda\\__init__.py", line 1205 in current_device\n' +
      '  File "<data>\\services\\comfyui\\ComfyUI\\comfy\\model_management.py", line 212 in get_torch_device\n' +
      '  File "<data>\\services\\comfyui\\ComfyUI\\comfy\\model_management.py", line 363 in <module>\n' +
      '  File "<frozen importlib._bootstrap>", line 488 in _call_with_frames_removed\n' +
      '  File "<frozen importlib._bootstrap_external>", line 1023 in exec_module\n' +
      '  File "<frozen importlib._bootstrap>", line 935 in _load_unlocked\n' +
      '  File "<frozen importlib._bootstrap>", line 1331 in _find_and_load_unlocked\n' +
      '  File "<frozen importlib._bootstrap>", line 1360 in _find_and_load\n' +
      '  File "<data>\\services\\comfyui\\ComfyUI\\execution.py", line 18 in <module>\n' +
      '  File "<frozen importlib._bootstrap>", line 488 in _call_with_frames_removed\n' +
      '  File "<frozen importlib._bootstrap_external>", line 1023 in exec_module\n' +
      '  File "<frozen importlib._bootstrap>", line 935 in _load_unlocked\n' +
      '  File "<frozen importlib._bootstrap>", line 1331 in _find_and_load_unlocked\n' +
      '  File "<frozen importlib._bootstrap>", line 1360 in _find_and_load\n' +
      '  File "<data>\\services\\comfyui\\ComfyUI\\main.py", line 250 in <module>\n'
  }
Developer (1 edit)

Thank you for sending the log! I would love to support AMD GPUs but I only have a computer with an NVIDIA GPU so it's difficult for me to test. If you would like to help me test AMD builds please send me an email via the mail icon in the game's description. Regardless, I will look into the code and see if there is an easy way to turn on compatibility for AMD GPUs

(+1)

I would really like a language option—for non-native English speakers—where the user could choose the language in which the AI generates text.

Developer

Hey Peterzs, not sure if this is possible but will look into maybe implementing it in a future update

Found a Bug:

Roxy is missing an eye in her PE Outfit with the "Happy" Expression.

Developer

That's pretty grotesque ahaha. Thank you for reporting this should be fixed in the update coming today or tomorrow

(1 edit)

Are you interested in adding more clothing options? Like winter clothes? Or more NSFW options, such as only topless looks?

Developer

Hey Peterzs, winter clothes wouldn't make sense at the moment since the game takes place over the spring semester (and I intentionally created a setting where it's always spring to avoid the need for cold weather outfits). A topless option is an interesting idea, if you prefer semi-clothed to fully nude you can use the default outfit generation with edited tags to produce an image like this then replace the nude outfit images with those

(+1)

I also like the idea of a custom outfit 2 slot. Could just alternate outfits by day. Also lingerie outfits would be incredibly peak.

Developer

Heavily considering adding custom outfit functionality in the next update, will keep everyone posted!

Another thing I’d like is the option to create chat groups on BunnyBord—specifically, the ability to form groups with more than one person after meeting certain requirements (such as becoming friends), which would make it possible to organize meetups with several people at once.

Developer

This is something that I would like to add in the future for sure. For now, you can organize meetups with several people by declaring one in the free text entry at the start of each timeslot. For example: Go to the beach with Celest, Ingrid, and Morgana. Make sure to check their schedules to see if they are free otherwise they will be dropped from the scene

It would be nice to have an optional background field at the start of the game to give the AI some context about your character to work with.

Developer(+1)

This is coming in the next update! Stay posted

(+1)

Something that also might be helpful is a way to interject a response before the official stopping since pretty often the narration has me reacting to character actions in ways I don't intend at all before it hands control back.

Developer(+1)

Also something that other users have asked for, should be coming soon

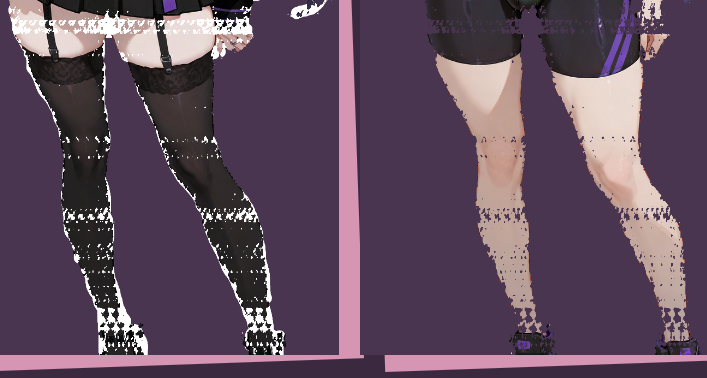
with a AMD 16gb GPU, I'm getting this weird transparency bug when generating images. it seem consistent every time. its in the same spots across all the images.

Developer

Hey Bobgone, another AMD user on Reddit reported a similar issue. I've had at least one user report the AMD generation is working fine, looks like they were using a 7900 GRE. I suspect this might be a hardware issue unfortunately, though I am looking into it still in case there's something wrong with our setup. Today or tomorrow's update will move the stale AMD version that is installed via the editor up to the newer version released by ComfyUI, fingers crossed that it fixes something.
Something else you can try is updating your AMD graphics drivers, ComfyUI github recommends updating them via this website: https://www.amd.com/en/support/download/drivers.html
Sorry that it still isn't working, I don't have an AMD computer to test on so I have no idea if these changes will work when they go out

(+1)

All good! Hope the update is going well I'm excited to try the actual game soon!

(1 edit)

with the openai i noticed while using koboldcpp that it keeps giving an error saying its using max context when it isn't for every generation when creating a character or even hitting the test button. also comfi ui sometimes isn't consistent with generations when re generating too. i had to switch to aurora llm at 16k context with quant 8.0 and it seemed to let me do everything in general good. but when switching to a max build i can't generate characters like using a 24b at 16k or using aurora at 32k context. seems like running a second agent in the background where you need to leave space for it to run. i will test running them normally when doing an actual game. so far just enjoying making the generations and characters!

this is on my 5060 ti 16gb

Developer

Hey ElPapaDon! Even when ComfyUI is idle, it reserves VRAM so that it doesn't have to re-load the models when you start up another generation. You can kill it by clicking the X button next to the ComfyUI status in Manage Characters. This will probably be really annoying if you are using local generation to generate the prompts for the characters, you will have to kill it every time before you start up the character prompt, but there really is no other way, unfortunately... I'd recommend using an online API for the char-gen stage if this is an issue.

In the next update I'll add a settings checkbox that disables ComfyUI auto-startup so you don't have to kill it every time before you enter a game

(2 edits)

gotcha! ill try using my 24b and kil it. honestly im fine with the button at the top in the character screen cause you made it easy to click the button anyways! right at the top and cant miss it!


EDIT: although i do see why you would make it an option to start without it on cause that makes it easier to continue off and get into the game at max llm! also does the comfy ui automatically assign if it goes to the gpu or the cpu? or is it only going to cpu?

Developer

I would assume GPU by default, CPU generation is veeeeery slow, you would know immediately

ok so far with testing i see that when ever i set the max context with a 32k in kobold but 12k in venus, it doesnt give me the error but i did notice it keeps trying to say its generating 12k every time. I tried creating a game multiple times and it would finish up till creating the schedule and venus would say the schedule is invalid so i switched to the google api just to create the run. i got the best result with L3.1-Dark-Reasoning-LewdPlay-evo-Hermes-R1-Uncensored-8B.Q8_0 at 32k but it still stopped at the schedule. im guessing it has something to do with setting the max context size in venus but not fully sure. so far when running the google api though i had no issues except a infinite loading at one point going to the next part of a day. ill mess around with it more today.

Developer(+1)

I had the exact same issue in my brief kobold testing with the class schedule. It kept refusing to generate unique class IDs for each class, that's why it kept failing for me. I think it's a model intelligence issue unfortunately, I was using a 24b model. 

And yes, koboldcpp is a little weird with context length, the "context size" you set when you open koboldcpp has to be enough to handle both input and output tokens, so the "max_tokens/length" setting in venus must be set to less than that. Basically, context > max_tokens + input tokens. 

Oh, and I wouldn't worry about koboldcpp when it says something like Generating[1/12000] tokens or something, that's just reporting the max content length, usually it ends early before it gets there

(+1)

gotcxha. should i use a different provider to run my llms like llmstudio or something if kobold is the problem

(1 edit) (+1)

and i used a 24b model also and it did the same... wondering if its just kobold not wanting to shake hands lol also conmfy ui for some reason still is not running in my gpu vram, only my regular system memory. is there a way to make it go to gpu first to make the process speed faster?

Developer (1 edit)

That is really weird. It should detect your GPU automatically. I would double check whether this is an issue with the game or with ComfyUI. You can manually run ComfyUI by going to data/services/comfyui/ and click run_nvidia_gpu_bat. It should open a GUI in your browser, drag in the following workflow:
https://github.com/venus-uni-dev/venus-uni-comfyui
And click run. You should be able to run it without having to download any of the models since it'll find the ones you downloaded through the game. The outputs should appear in data/services/comfyui/ComfyUI/output
If it's still not using your GPU there, I'd look up online about your GPU and ComfyUI and see if anyone else is having similar issues

(+1)

i noticed it does run on my graphics card but doesn't show normally. i had to research it alot but im good! i just thought it would be faster to generate stuff lol.

(+1)

DeepSeek API gives HTTP 400 with OpenAI-compatible endpoint

Hi! I really like the game so far. I tried using my paid DeepSeek API key instead of Gemini.

Settings I used:

When I click Test connection, I get: “Custom endpoint rejected the request (HTTP 400).”

DeepSeek's API is OpenAI-compatible, so I was wondering whether there is something in the request that isn't compatible with DeepSeek yet.

It would be great to have DeepSeek working as a custom provider, since I already have a paid DeepSeek API key and really like the game.

Thanks!

(+1)

Yeah, that happens sometimes, either your reasoning is too high, which takes too long. 
but then if you are using mimo 2.6 pro and glm 5.1. Reasoning has to be set to high or they won't work. 
Deepseek 4 flash works, AFTER several retries. 

Developer

Hey Orange, glad to hear you're enjoying the game. I'm not quite sure what's happening based on that message alone. Can you check the app.log? Maybe it has a more specific error in there

(+1)

2026-09-23 16:44:53.437 main     LOG   [llm] → Custom endpoint models: https://api.deepseek.com/v1/models

2026-09-23 16:44:58.757 main     LOG   [llm] → Custom endpoint deepseek-flash (thinking=medium, tier=standard, maxTokens=65536, schema=connection_test)

2026-09-23 16:44:58.757 main     LOG   [llm] → system: (truncated, 20 chars)

2026-09-23 16:44:58.757 main     LOG   [llm] → user: Ping.

2026-09-23 16:44:59.089 main     LOG   [llm] ✕ Custom endpoint deepseek-flash HTTP 400 after 332ms

2026-09-23 16:44:59.089 main     ERROR [ipc] llm:testWriter failed: {

    code: 'LLM_REQUEST_REJECTED',

    message: 'Custom endpoint rejected the request (HTTP 400).',

    detail: 'invalid_request_error This response_format type is unavailable now'

  }

Developer

So, apparently deepseek API does not support json_schema output type. That means that the API is wholly incompatible with our game unfortunately. If you want to use deepseek models, I tested using them through OpenRouter just now and it seemed fine. Sorry about this

(+1)

ChatGBT made me a local proxy that converts the response format into a compatible one with deepseek, so I can actually use DeepSeek without needing to get it through OpenRoutner. So no worries.

Developer

Great! Glad it's working

(+1)

Can I have a feature, where girls sends pics in the texting feature. 

O-O 

Because no judging i like sharing my girls, and i need pics when they go on dates with other suitors O-O 

Developer

I considered features like this during dev but image generation during gameplay is expensive and slow, unfortunately. However, I am thinking about ways that it could be possible, because I think this kind of feature is really cool! Maybe in the future

(+1)

The ability to post on Bunnybook would be a cool feature, you could @ girls and have others respond, etc.

Or just post thoughts/goings on and have them respond.

Maybe a post like "Thinking of hitting the beach if anyone's up for it?" could lead to a hangout?

Developer(+1)

Hey furbomber, I experimented with this in development and it was a bit too complex to manage for Early Access. Definitely a feature I'm considering in the future

(2 edits) (+1)

What open source model did you use, and were you able to get it to make a new game? I have 24GBs of RAM, but I'm unsure what backend to use and with what parameters as I keep getting a connection lost mid way through or something about the generated class catalog was not usable. Failed: the class catalog

Would be really cool if in future you could add additional context when creating a game to specify certain elements, or modify the context of existing characters

Additionally to force end a scene as I'm stuck in an infinite loop essentially, retry a scene if the ai messes up too

Developer

Hey es4rtg, I don't use local backends to play, I only use Gemini Flash 3.8 through Google AI Studio. If you're getting generated class catalog was not usable, more likely than not your local backend is duplicating class codes for certain classes. This can be an intense task for most models since it generates dozens of classes that all need their own unique class code. I've recommend to other users to use a frontier model for starting your game, then switching back to your local backend once you've scheduled your classes.

Character profiles are coming in the next update! I've already played as a celebrity and a talking cat.

Usually I'm able to "force end" a scene by saying that I'm going home or something. The LLM is supposed to classify the scene as over and end the scene. If this isn't working, your model is likely not getting the hint that it should end the scene

(1 edit)

That's really good and looking forward to the next update, it's a brilliant project so far!


A few other things - Is 127.0.0.1 hard coded? I can't seem to get it to work over my local network but it works fine on the same device (Got it working by opening a local proxy on my client device - netsh interface portproxy add v4tov4 listenaddress=127.0.0.1 listenport=5001 connectaddress=(HostIP) connectport=5001 - & then using http://127.0.0.1:5001 to connect (KoboldCPP) which worked

Hopefully you've changed your API key as there seems to be one for Gemini in the .json file, unless that's a placeholder

Definitely worth adding a re-swipe since I can see what you mean by local are lackluster compared to Gemini, I found Gemma 12B IT Heretic GGUF Q6 to be quite good and it gives me the generation speed, but it does mess up once in a while so that & a force end would be amazing

One other bit of feedback is allowing the option to keep memory of previous events or changing how pre-determined events are created, maybe having it done when the scene is created rather than being statically baked in the initial generation - For example, if you've been talking about something specific with characters the morning/night before, and then go to visit their dorm, one of mine was pre-written text about them never meeting me before (Gemini Flash 3.6 Lite)


Again really good project, keep it up

Developer (1 edit)

Um, please send me an email or private message about the Gemini key in the json file, I think I know what you're talking about but if I really did expose a key that's definitely NOT intended and I need to remove it asap.

I didn't hardcode anything for the endpoint, but we do add /chat/completions to the end. This seems to work for koboldcpp, I didn't find any backends in my quick research that this would be a problem for, but if it's a problem for your backend definitely let me know.

You can currently re-swipe by loading the last autosave and typing in your action again

In the next update, you'll be able to manually edit character memories! Stay tuned

(+1)

Hi again, I've sent you an email


The issue seems to happen on KoboldCPP with a header error, but after doing that fix, it works seemlessly on KoboldCPP & Llama.CPP, if someone else has the problem then that fix is there readily available


Hopefully the new update is out soon as it sounds like really big improvements are coming, I'd love to see the ability to modify temperature and other parameters to adjust outputs as I'm now using Qwen 3.8 27B, it works exceptionally but the dialogue is very strange 


Developer

Glad to hear it's working! Aside from temperature, what other parameters would be useful? I hate UI bloat and opening the koboldcpp generation menu gives me a headache. I'd like to avoid that and only include the useful stuff

(+1)

Definitely frequency & repetition penalty modifiers would be great to see, maybe a system prompt input to further help direct a local language model to help it write a certain way, or ensure it uses sprites, change backgrounds & actually end the scene

top P & k too, but that might be a stretch as that's going into ui bloat

Also the Gemini Key problem was something on my end so that's of no concern and that's my bad

Developer

No worries! And thank you for your feedback, I will add it to the dev plan

Hello! First of all, thank you for adding OpenRouter support. Now I can finally enjoy this game!

I tried to use GLM 5.2, but for some reason it just can't properly swap backgrounds, show character sprites, or end the day. But I switched to Gemini 3.8 Flash, and everything is working incredibly well, even though it's slightly more expensive.

So, I'd love to see a few things added to this game:

  1. Different ways of background generation. I don't have any way to create or top up a Gemini API key, so it would be nice to have some different ways of generating backgrounds. Maybe another ComfyUI workflow? Or through the OpenRouter image endpoint?
  2. Manual saving and save management. It would be nice to be able to manually create, delete, and rename saves to have more precise control. It would also be nice to be able to roll back through some dialogue or scenes during a single event, for example using the log window, or simply by scrolling the mouse wheel, like in most visual novels.
  3. Debug menu. I'd love to see a proper debug menu, with features like precisely monitoring and controlling the system prompt, model responses, and the generation process, as well as being able to abort the generation if something goes wrong, and some other stuff! (Once, I had Gemini stuck in a loop repeating itself. In-game it only looked as if the message was loading, but in the background, it wasted 65k output tokens, hitting the output limit...)

Still, the game looks great, and I'll be looking forward to future updates!

Developer (1 edit) (+1)

Hey Hapi! Glad it's working a bit better for you now, I personally only use Gemini 3.8 Flash because the speed and quality is totally worth the price to me. If you don't mind me asking, why aren't you able to create an API key? You should be able to sign up and create one for free as long as you have a Google account... I'm assuming it's something like it's not available in your country?

Anyways, I don't mean to pry. For your suggestions:

1. For background generation, you can generate (or find) images outside of the game first. Then, go into the Edit Character modal and click the folder icon under the name. Place them in the character's folder as room_day.png and room_night.png next to character.json. I actually just tested this and it works great!

2. Manual save management is on the list for development. But rewind is already in the game for next update! Stay tuned

3. In the next update, you'll be able to do things like edit the returned response, insert a new action at any point in the reply, and edit character memories. Stay tuned! Allowing system prompt editing is also an interesting idea, definitely considering this. Sorry to hear about that Gemini bug, you can abort the prompt by loading the last autosave or returning to the main menu during generation.

(+1)

Yeah, Gemini isn’t available in my country, so I’m kinda left out there, heh. Thankfully I can still use it through OpenRouter, so it’s not really a problem!

Also, I tried generating the backgrounds manually, and it actually turned out to be really convenient, so thanks for the tip!

And the next update already sounds really promising. I’m definitely looking forward to it!

(+1)

A JavaScript error occurred in the main process, Uncaught Exception: Error 'zoomFactor' must be a double greater than 0.0 at applyStageZoom (E:\games\VenusUniversity\resources\app.asar\out\main\index.js:6663:19) at BrowserWindow.<anonymous> (E:\games\VenusUniversity\resources\app.asar\out\main\index.js:6742:33) at BrowserWindow.emit (node:events:514:28)

 I get this popup error message if I click away from the screen (multi monitor) and then back onto it again, I think it happens if it tries to minimise the game window/screen?

Developer

Hey bmadgett, thank you for reporting this! I also got this during testing but was unable to reproduce. Will try and fix for the next update

(+1)

Am using a NanoGPT sub and tried various models from there. If I use 'Quick Start' then the game runs fine (eg using the DeepSeek R1 model). But if I try 'New Game', picking the students manually, it just hangs for ages (10+ mins) at 'Generating Class Schedule' and eventually comes back with a 'generation failed' type message. This is whatever model I've tried - smaller ones, large ones, coding-focused, RP-focused, etc. I know probably you'll say 'Use Gemini' but shouldn't one of these other models also be capable of reasonable JSON or whatever it is you're looking for in the responses? Why does it take so long to fail, also? Any debug I could look at to narrow down what's going wrong?

Developer (2 edits)

You can download an app.log from the main menu by clicking Feedback (or checking data/app.log). Usual culprits for generation failed are the model not returning unique class IDs for each class. Deepseek R1 shouldn't have a problem unless you're running it locally though, that's weird. On Gemini Flash 3.8, the prompts finish in under 30s

(3 edits) (+1)

Some suggestions/questions, not sure if they are covered anywhere! 

1) Any plans on having a discord for people or the equivalent?

2) It would be nice to have the option to interject/go back/regenerate/clarify things that are said. While the system works 95% of the time extremely well, sometimes the AI will take the scene in a direction that I don't want it to go (or I want to interject before it goes a certain way) and it'd be nice to be able to force the text box to appear to head it off or even a way to go back a message or two. I understand that might not be a direction you want to take the game in but wanted to bring it up. 

3) Note, I have not finished a full semester yet. I think it would be cool if you could have character cards generated for like Silly Tavern, etc. once your semester ends with them (with their memories of the player) that you can continue to chat with them OR have an in-game way of doing so after the semester ends.

4) Any plans to add romanceable or non-romanceable males to the game?

Developer

1) There won't be an official Discord because I have 0 desire to moderate one. But people are more than welcome to create communities for the game, and I'd be happy to link them on the page.

2) Coming in the next update! You'll be able to rewind, edit LLM output, and insert a prompt at any point in the conversation. Stay tuned!

3) Exporting a character as a SillyTavern card is a feature I'd love to implement in the future. There's currently no plans for content after the 1st semester, but it's not impossible. Maybe sometime in the far future

4) The next update adds fine-grained generation settings which will technically allow you to generate guys. I've already been able to make one on the new update, but unfortunately the body types are quite limited: since we use pose data generated from girls, you'll only get guys with pretty feminine proportions. This isn't something I plan on supporting too much, but it will at least be somewhat possible

Viewing posts 1 to 20 of 26 · Next page · Last page